Stop AI Coding Agents From
Forgetting Your Architecture.
Cut your Cursor, Claude Code, Windsurf & Aider token bills by 70–90% while preventing context amnesia and broken imports. Powered by sub-15ms In-RAM AST Call-Graphs, $0 offline local GPU syntax audits, and Caveman to Modern-Man JIT output transformation.
Zero global dependencies required • Runs instantly on Node & Python 3
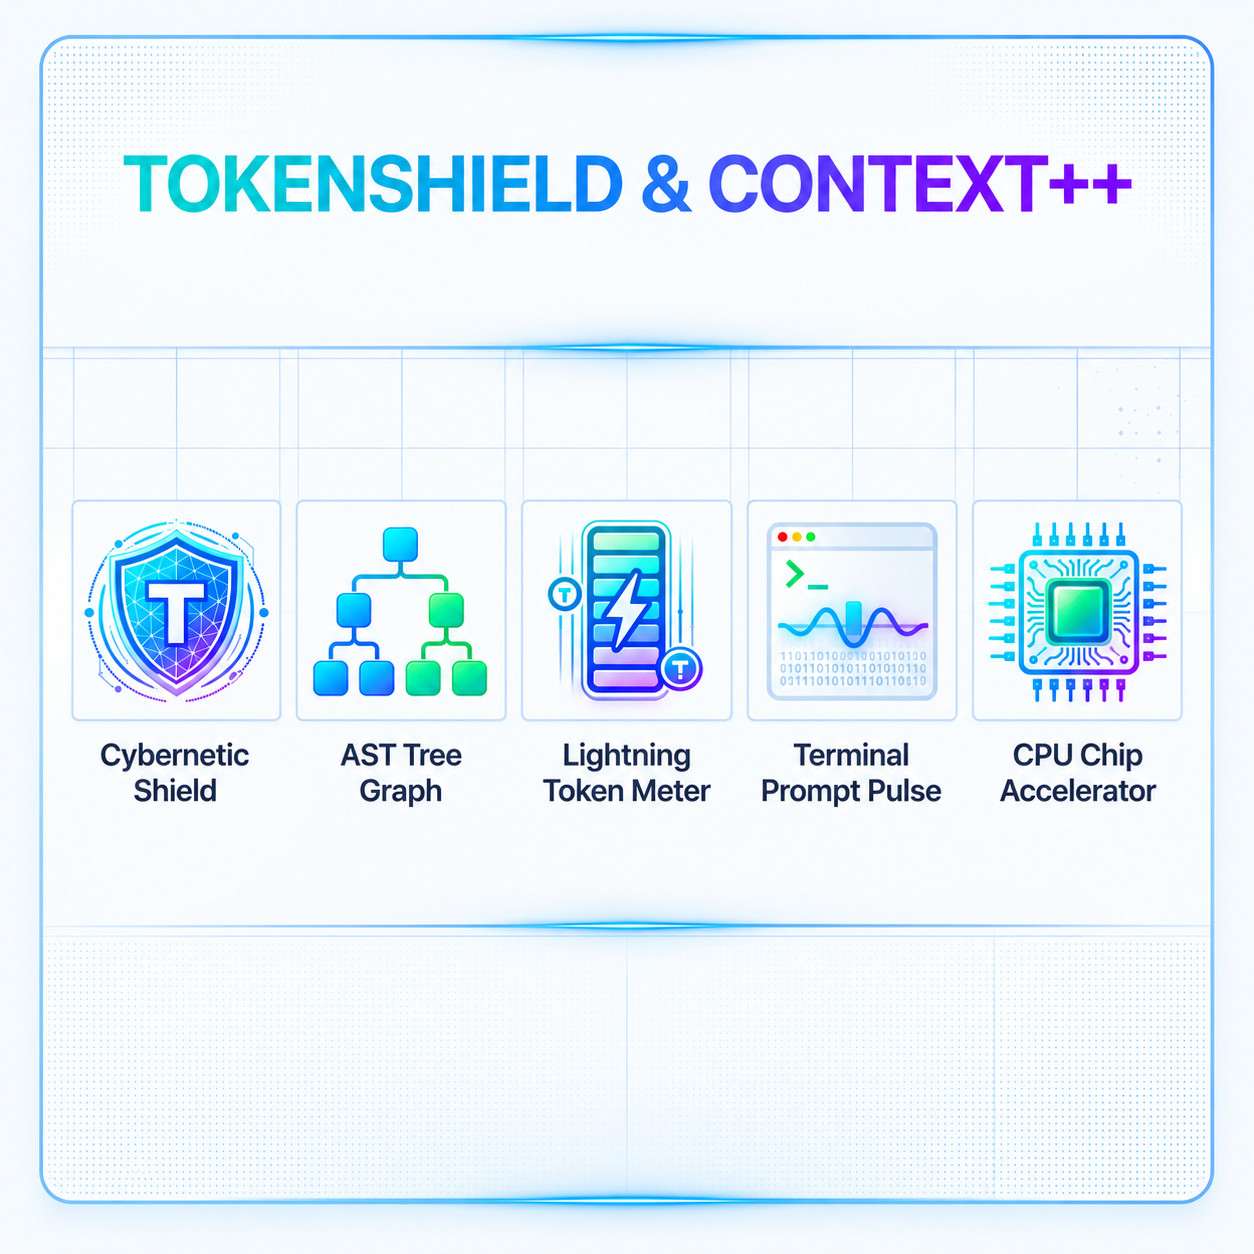
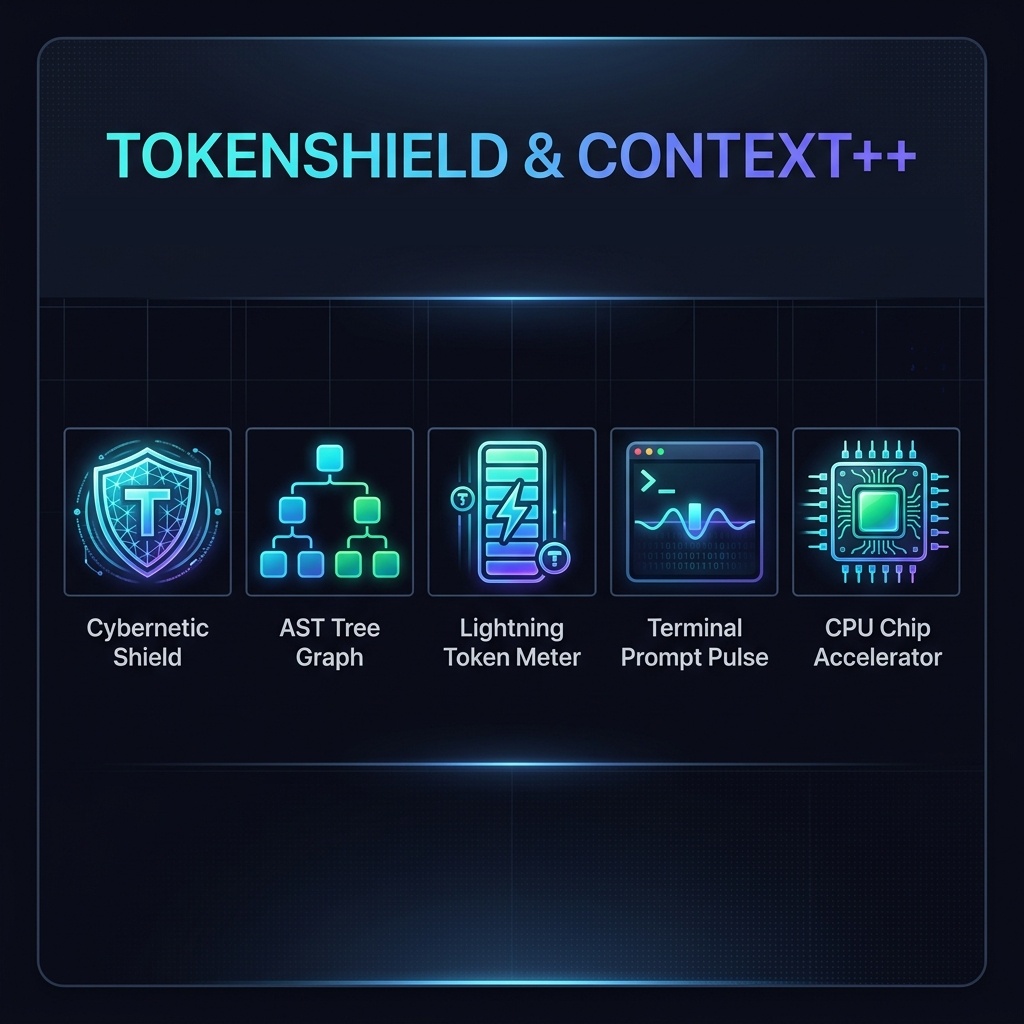
5 Modular Engines • Unified Architecture
Master Shield • In-RAM AST & Redis RAG • Token Meter • Context Pulse • Neural Chip
Standalone Visual Identity
Modular, standalone high-res cropped assets powering the TokenShield engine
TokenShield Emblem
Master Core
AST Tree Graph
In-RAM SQLite + Redis + LLM
Token Meter
ROI Economizer
Terminal Pulse
Context Carry-Over
Neural Chip
Local GPU Pre-FlightUniversal Support Across All Major AI Coding IDEs
TokenShield isn't confined to a single marketplace. Whether you code in Cursor, Windsurf, Claude Code, Antigravity, or JetBrains, TokenShield hooks seamlessly into your editor.
1-Click install from the official VS Code Marketplace or manual install via direct VSIX download. Includes live sidebar dashboard and bottom status bar token counter.
code --install-extension tokenshield.vsixNatively available via Cursor's Open-VSX registry. Drag & drop the VSIX or search “TokenShield”. Automatically configures .cursorrules to stop context amnesia.
cursor --install-extension tokenshield.vsixConnects straight to Windsurf Cascade. Full In-RAM AST Call-Graph lookups and surgical diff filtering. Automatically updates .windsurfrules.
windsurf --install-extension tokenshield.vsixNo marketplace needed! Run 1 command to register TokenShield as a native Model Context Protocol (MCP) server in Claude Desktop and Claude Code CLI.
npx tokenshield setup-mcpPre-configured in .agents/mcp_config.json. Provides dense semantic search, offline GPU pre-flight linting, and AST reference lookups.
npx tokenshield self-installConnect IntelliJ, PyCharm, WebStorm, or Zed via standard JSON-RPC Stdio MCP. Or launch the standalone interactive Terminal UI (TUI) cockpit for any CLI tool.
npx tokenshield tuiRaw AI Agents vs. Agent + TokenShield & Context++
See the exact difference between letting Cursor / Claude Code blindly resend entire files versus routing queries through local In-RAM AST filters.
| Architectural Metric | Raw AI Coding Agent (Cursor / Claude) | With TokenShield & Context++ | Net Impact |
|---|---|---|---|
| File Inspection & Symbol Lookups | Dumps entire 50KB–200KB source files into context (~45,000 tokens) | Extracts precise AST function signature & line number in RAM (~180 tokens) | 99.6% Token Cut |
| Lookup Latency | 4–8 seconds (Remote Cloud LLM vector search + generation) | 8.35ms (In-RAM SQLite BM25 index on local hardware) | 500x Faster |
| Cost Per Architectural Turn | $0.45 – $0.90 per prompt turn on Opus / Sonnet 3.5 | $0.002 per prompt turn (zero tokens wasted on boilerplate) | 76% Bill Reduction |
| Context Window Degradation | Model fatigue & amnesia after 10–15 turns (forgets turn 1 conventions) | Context stays clean under 20k tokens across 100+ continuous turns | Zero Amnesia |
| Syntax & Pre-Flight Verification | Burns paid tokens rewriting code to fix missed semicolons and typos | $0 offline local GPU/CPU linter catches syntax errors before sending | 100% Free Verification |
| Git & Patch Diffs | Transmits whole files or large 500-line multi-page chunks | Surgical diff economizer trims down to minimal 15-line unified patch | 84% Smaller Diffs |
| Output Token Waste & Prose Fluff | Generates 800–1,500 word conversational fluff @ $15/1M output cost | Caveman economizer slashes 60–80% output tokens; local LLM decompresses for $0.00 | 80% Output Savings |
| Multi-Machine Memory Transfer | Lost on terminal restart or switching from Laptop to Desktop | npx tokenshield chat push/pop & export bundle across machines | Permanent Vault |
Why Naive Prompt Minifiers & Regex Comment Strippers Fail
- •The Prompt Bloat Paradox: Dumping AST skeletons into static
AGENTS.mdor instructions actually adds hundreds of tokens to every single prompt turn. - •Zero In-RAM Caching: Re-scans disk on demand with slow node loops; no raw-socket RAM cache or instant symbol graphs.
- •Still Burns Tokens for Syntax: Cannot verify code locally—wastes expensive Claude 3.5 Sonnet / GPT-4o calls on missing brackets and typos.
- •Zero Prompt Overhead: Intercepts queries at the socket layer before they hit the wire. No massive instruction files clogging context.
- •In-RAM Redis + SQLite BM25: Returns exact symbol definitions across 4,400+ files in <15ms with 0.1ms socket cache hits.
- •Local GPU Pre-Flight: Audits syntax via local Qwen2.5-Coder in <1s at $0 cost before sending anything to the cloud.
It's Not Black Magic.
It's Using The Hardware You Already Paid For.
Your workstation has 32GB–64GB+ of ultra-fast DDR5 RAM and a local GPU sitting at 2% utilization. Yet every time an AI agent helps you code, it blindly dumps megabytes of raw files into paid cloud LLM windows. Here is how TokenShield sits between your editor and the cloud to slash your bill.
The Interceptor Nexus
Positioned directly between Cursor/VS Code and the Cloud LLM API
Blind File Transmission
You ask: “Where is verifyEntitlement called?”. Raw agents don't know your AST, so they ingest 10–20 entire source files (~60,000 cloud tokens = $0.90) just to read a 3-line import.
Hybrid Dense + Sparse Interceptor
Hooks into .agents/ and MCP protocols. Queries an In-RAM SQLite BM25 index for exact symbols, runs dense vector estimation via local embeddings (BGE-M3/Qwen) in the execution path, and hits an In-RAM Redis fast-cache (< 0.1ms).
Lean 180-Token Context
Only the exact definition snippet and call-site line numbers are passed to Claude/Cursor. 99.6% token reduction, zero context fatigue, and zero amnesia on turn 50.
Dense Semantic Estimation + In-RAM SQLite BM25 + Redis Cache
Why pay cloud vendors to parse your code when your system RAM operates at 50 GB/s? TokenShield mixes and matches three complementary layers: (1) In-RAM SQLite FTS5 BM25 for deterministic sub-3ms exact symbol lookups, (2) Dense Vector Estimation powered by local embeddings (BGE-M3 / Qwen in the execution path) for fuzzy semantic queries, and (3) an In-RAM Redis raw-socket cache (< 0.1ms) that serves repeated queries at zero CPU cost.
Offline Local GPU Pre-Flight Linting
Stop spending $0.05 every time an AI agent generates code with a missing bracket or typo. TokenShield routes pre-flight syntax audits to your local GPU (via LM Studio or Ollama) or native CPU validator in < 1 second.
Live Work State Vault & Anti-Amnesia
Eliminate the repetitive “re-explaining your architecture” token tax. TokenShield continuously encodes in-flight touched files and active milestones into .agents/live_work/.
Surgical Diff Economizer & Patch Verifier
AI models frequently rewrite 600 lines of code just to alter 2 lines. TokenShield extracts lean unified patches, runs dry-run git apply --check collision verification, and trims edit tokens by up to 95%.
Caveman to Modern-Man: Just-In-Time (JIT) Dual-Engine Transformer
Output tokens cost 3x to 5x more than input tokens on frontier cloud LLMs (Claude 3.7 Sonnet @ $15/1M, GPT-4o @ $10/1M, o1 @ $60/1M). TokenShield activates Julius Brussee's canonical Caveman prompt to instruct cloud models to draft all technical reasoning in ultra-terse, high-density fragments—cutting expensive output tokens by 60%–80%. Then, TokenShield's Caveman-to-Modern-Man engine auto-transforms the output Just-In-Time into articulate, friendly, and complete Modern-Man developer walkthroughs on your local GPU/CPU (Ollama / Qwen2.5-Coder / LM Studio) at $0.00 cloud cost and 0 cloud tokens!
$ tokenshield input on/off$ tokenshield output on/off$ tokenshield interpreter on/offAST Blast Radius & Ripple Guard
Before your AI agent modifies a shared function or type, TokenShield analyzes downstream callers and dependent files in <5ms. It computes exact call-sites and flags risk levels (High, Medium, Low) to prevent silent breaking changes across large repositories.
AST File Outline Virtualizer
Stop AI agents from burning 10,000+ tokens reading full 1,000+ line files just to learn class structure. TokenShield extracts a virtual outline of classes, methods, signatures, and line numbers in <10ms—slashing input tokens by 90% while giving full structural comprehension.
Digital Deliverable & Engine Pack
Everything you receive immediately upon activating your TokenShield & Context++ Lifetime License.
Standalone CLI Engine
100% Python standard library & Node CLI (tokenshield-contextplus). Zero pip packages, zero npm bloat, instant cross-platform execution on Windows, macOS, and Linux.
Cursor & VS Code Plugin
One-click install into Cursor and VS Code with live status bar token telemetry pill, offline code linting command, and real-time AST symbol search.
2-Page Cryptographic Activation Pass
Official downloadable PDF with personalized Ed25519 license key, instant QR unlock scan, offline developer CLI cheatsheet, and team entitlement record.
In-RAM AST + Redis + Local LLM
Triple-tier retrieval: SQLite FTS5 BM25 index across 4,400+ files, In-RAM Redis socket cache (< 0.1ms), and local dense vector estimation (BGE-M3/Qwen) with 0 cloud tokens.
Dual Local Model Bridge
Automatically detects and orchestrates LM Studio (port 1234) or Ollama (port 11434). Falls back seamlessly to native CPU AST engine if no GPU is active.
1-Click Low-RAM Mode
Instantly frees 8GB–14GB RAM on developer laptops while preserving 100% of token-saving AST RAG lookups with 0 lag.
Caveman to Modern-Man JIT Transformer
Pairs Julius Brussee's viral Caveman compression (60–80% output token savings) with TokenShield's Just-In-Time Local Transformer to auto-convert terse notes into professional Modern-Man developer walkthroughs on demand ($0 cloud cost).
AST Blast Radius & Ripple Guard
Analyzes downstream callers and dependent files before editing shared symbols. Provides instant risk tier ratings (Low, Medium, High) in <5ms to eliminate breaking changes.
AST File Outline Virtualizer
Provides AI agents with instant 100-token structural skeletons (classes, methods, signatures, docstrings) instead of reading entire 1,000+ line files, cutting input tokens by 90%.
Experience In-RAM AST & Local Verification
Click any command below to simulate how TokenShield intercepts agent queries in sub-15ms before they reach the cloud.
Financial Calculator
Calculate Your Monthly Token Savings
Drag the slider to match your team's current monthly AI coding agent bill
With a one-time $29 Lifetime license, TokenShield pays for itself in less than a week, and saves you money every single month forever.
The Production Origin Story
Why we were forced to engineer TokenShield while scaling PortSync alongside modern apps like Animal Vision and Thermal Camera.
When Codebases Grow, Models Hit a Wall
As our unified multi-repo architecture grew across 4,400+ files and 4 interconnected workspaces, frontier models (Claude 3.5 Sonnet, GPT-4o, Cursor) suffered severe breakdown:
- No Model Can Hold 4,400 Files in Active Memory: Context rot caused models to forget foundational architecture, break existing imports, and hallucinate outdated conventions.
- Crushing Token Bills: Asking simple questions like "Where is this route invoked?" dumped 50KB–200KB source files into context on every turn, racking up hundreds in weekly API costs.
- Model Fatigue & Endless Rewrite Loops: After 15 turns, agents forgot what they wrote in turn 3, rewriting working code into broken syntax.
We built TokenShield out of pure necessity. By indexing AST call-graphs into sub-15ms local RAM (SQLite BM25), pre-flighting syntax locally on GPUs/CPUs at $0 cost, and carrying context across sessions, our AI agents went from fatigued to laser-focused.
Real-World Benchmark (PortSync Monorepo)
Modular Component Toggles & Low-RAM Mode
Developers have different machines. On a 8GB–16GB RAM laptop? Toggle off heavy local LLMs with one command while keeping sub-15ms AST RAG active!
Disables local LLM checker; keeps ultra-fast In-RAM AST RAG and zero-RAM native linter.
Hybrid AST RAG & In-RAM Redis
ACTIVECompiles workspace syntax trees into SQLite BM25 + In-RAM Redis socket cache for sub-15ms symbol, caller, and dense semantic searches.
Local LLM Code Checker
ACTIVEConnects to Ollama or LM Studio to pre-flight syntax and edge cases offline before sending diffs to cloud APIs.
Native AST Syntax Validator
ACTIVEZero-dependency Python AST parser checking syntax, bracket closures, and indent parity on any CPU.
Surgical Diff Economizer
ACTIVEExtracts lean unified patches so agents only transmit 15 changed lines instead of 200KB whole files.
Session Context Compactor
ACTIVECompacts conversation memory so agents never hit 200k context limit or lose earlier decisions.
Live Usage & ROI Telemetry
ACTIVELogs active session timer, tokens saved, and dollar savings to CLI, VS Code status bar, and local JSON vault.
Where Telemetry & Savings Are Displayed
Never guess how much you are saving. TokenShield reports metrics across 4 native surfaces.
1. Developer CLI
Run npx tokenshield telemetry for instant session duration, tokens spared, and dollar ROI.
2. VS Code / Cursor Pill
Bottom status bar widget shows live pill:
[TokenShield: 320.91M saved ($962.74)]
3. Local JSON Vault
Logged offline in ~/.tokenshield/vault.json for corporate and team auditability.
4. Web Unlock Portal
Instant activation verification, QR license binding, and machine seat management via web portal.
TokenShield Switchboard • IDE Plugin Preview
Real-time Token Budget Gauge & Sub-Category Consumption Inspector
Simple, Lifetime Developer Pricing
Pay once, use forever. Includes immediate access to the standalone CLI, IDE extension, and official 2-Page Activation Pass PDF with QR unlock.
Personal Indie Pro
For solo builders, freelancers & indie hackers
- UNLIMITED Lifetime Token Savings
- 1 Developer Seat (3 Devices: Work PC, Laptop, Mac)
- In-RAM AST Call-Graph RAG (< 15ms lookups)
- Offline Local Model Manager (LM Studio + Ollama)
- Modular Low-RAM Mode (Saves 8–14 GB RAM)
- Chat Context Carry-Over (Push, Pop, Save, Export)
- Official 2-Page Activation Pass PDF with QR Unlock
🔒 Instant license key delivery via email • Free evaluation mode — try it in your editor before you buy
Team & Agency Edition
For software teams, design shops & agencies
- Everything in Indie Pro, PLUS:
- 5 Developer Seats (3 devices per seat = 15 total devices)
- Commercial Agency & Client Project Use Rights
- Multi-Workspace & Monorepo Centralized Indexing
- Automated FIFO Device Rotation (16th device rotates)
- Lifetime Engine Updates (Zero Subscriptions)
🔒 Instant license key & PDF activation pass generated immediately
Frequently Asked Questions
Technical details, privacy guarantees, and hardware compatibility
How does TokenShield cut API token costs by 70–90%?
AI coding tools like Cursor, Claude Code, and Windsurf repeatedly send entire 50KB–200KB source files into the context window just to check a function signature or find where a class is defined. TokenShield compiles your AST call-graph into local RAM using SQLite BM25. When the agent asks for references, TokenShield serves exact 5-line snippets in under 15ms without sending 50KB files to the cloud.
